Skip to content

Why 80% of Tests Never Influence Strategy
The common explanation for why most A/B tests don’t shape strategy is that most A/B tests lose. Simple story: you run a test, it doesn’t win, so obviously it doesn’t influence anything downstream. Nothing to see here.
Actually, that explanation doesn’t hold up against the numbers, and it lets a much bigger problem hide behind a much smaller one.
The numbers everyone quotes and what they mean
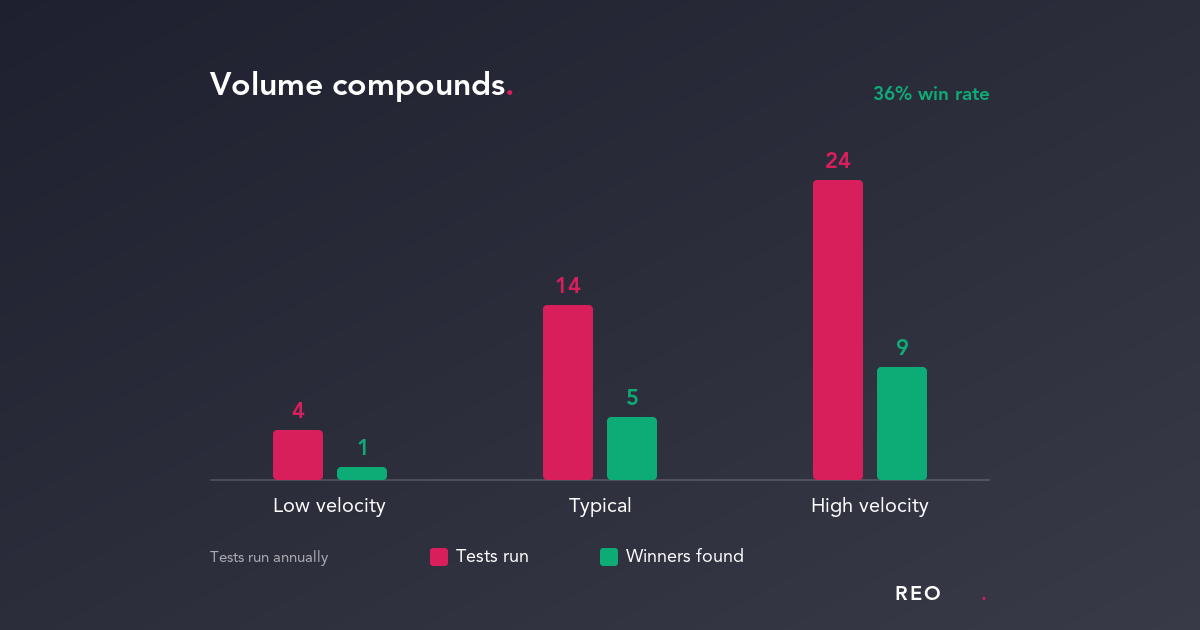
Optimizely’s analysis of 127,000 experiments across 1,100 companies found that only 12% of tests win on the primary metric, with average win rates of roughly 20% across all experiments and 10% for revenue-tied tests specifically. Separately, 35-40% of experiments reach a statistically conclusive result of any kind, win or lose. VWO and CXL’s independently reported benchmarks land in a similar 25-30% win rate range. And this isn’t a sign of amateur programmes: Microsoft and Google’s own experimentation leaders report that in well-optimised products, only 10-20% of changes produce a positive effect on the target metric. A 10-20% win rate is the expected state of a mature programme, not evidence of failure.
Here’s the detail that gets lost every time someone quotes the headline number: conclusive rate and win rate are not the same thing, and neither of them is the same thing as “influenced strategy.” A test can lose decisively, with a clean, statistically significant result, and still tell you something strategically important. A test can win, get shipped, get celebrated in a slide, and never once inform another decision after that.
→ Roughly 40-45% of tests are inconclusive, no measurable effect in either direction, according to consolidated CRO benchmark data from VWO and CXL. That’s not the same as “wasted.” An inconclusive result on a hypothesis your team believed strongly in is genuinely useful information. Most programmes don’t treat it that way, they file it as a non-event and move on.
→ Optimizely’s own 127,000-experiment analysis found that search functionality tests had the highest expected impact of any category, 2.3%, yet appeared in only 1.3% of experiments run. That’s a prioritisation failure, not a win-rate failure. The highest-leverage category of test was almost never run, which means its absence from the strategic conversation had nothing to do with whether it would have won.
→ Top-quartile testing teams document a hypothesis before every test (“we believe X will improve Y because of Z”) at a 78% rate, compared with 34% for average teams, per CRO benchmark research aggregated across agency data. Without a documented hypothesis, a test result has nowhere to attach itself in the organisation’s collective understanding. It’s a data point with no home, so it can’t influence anything beyond the immediate test.
The maths nobody puts in the business case
It’s not the win rate. It’s the reporting gap between “test concluded” and “someone with authority over the roadmap heard about it and changed their thinking.”
Consider how this plays out even at the most sophisticated experimentation organisations. At Microsoft’s Bing, an employee’s proposed headline change was judged low priority and sat shelved for months, until an engineer finally ran it as an A/B test. It lifted revenue by 12% and became the most valuable idea Bing ever shipped, worth an estimated $100 million (Kohavi and Thomke, HBR). The bottleneck wasn’t testing capability. It was the judgment layer deciding what deserved attention.
Most testing programmes report results one way: to the immediate team, in a testing tool’s dashboard, as a win/loss/inconclusive tag. That’s a long way from a boardroom, a quarterly planning session, or a category strategy document. A test result has to survive translation through several layers, from raw statistical output, to a written insight, to a recommendation, to something a non-CRO stakeholder actually reads and acts on, and most results die somewhere in that chain, regardless of whether they won.
This is precisely the gap REO’s client enablement work is built to close. Clients moving from full outsourcing to an internal centre of excellence consistently underestimate how much of “strategic influence” is a communication and documentation problem rather than a testing-quality problem. A programme with a mediocre win rate but excellent internal reporting will shape strategy more than a programme with an excellent win rate and no consistent way of surfacing what it learned.
What breaks the chain, specifically
→ No shared evidence library. If test results live in individual testing tool accounts rather than a searchable, structured record, insights only ever reach the people who happened to be in the room when the test concluded.
→ No connection between test result and business metric stakeholders actually track. A conversion rate lift on a PDP means little to a CFO unless someone translates it into projected revenue impact, and that translation step is frequently skipped or done inconsistently.
→ Inconclusive and losing tests get zero write-up. Teams that only document wins are actively discarding most of their strategic evidence, since 80-90% of tests fall into the loss or inconclusive bucket by industry benchmark. That’s the majority of your organisational learning, thrown away by default. REO writes up every test, win, loss or inconclusive, with insights structured to feed subsequent tests as a reusable evidence source, which is what stops that learning leaking away.
→ No cadence for surfacing patterns across tests. A single test rarely changes strategy. A pattern across six related tests, users consistently distrust a certain page layout, users consistently want more delivery information earlier, often does. Without a habit of reviewing test history for patterns, that signal never accumulates into anything decision-makers see.
The reframe
If 80% of your tests aren’t influencing strategy, the fix probably isn’t a higher win rate. Win rate is bounded by how mature your programme already is and how much low-hanging fruit remains. The fix is treating every test, win, loss or inconclusive, as an input to a documented, searchable, translated body of evidence that someone outside the testing team actually reads. That is what data driven decision making actually looks like in a testing programme, not a slogan on a slide.
Which raises the real question for most programmes: when a test loses this month, does anyone outside the immediate team ever hear about it, and if not, what exactly is the 80% of tests that don’t win actually being spent on?
FAQs
Why don't most A/B test results end up influencing business strategy?
Not because most tests lose. It’s what this piece calls the reporting gap, the space between a test concluding and someone with authority over the roadmap actually hearing about it and changing their thinking. Results tend to get logged in a testing tool’s dashboard for the immediate team only, and rarely get translated into a documented insight that reaches anyone beyond it.
What percentage of A/B tests actually win?
Optimizely’s analysis of 127,000 experiments puts it at roughly 12% winning on the primary metric, with a 20% average win rate across all experiments. VWO and CXL‘s benchmarks land at 25-30%, and Microsoft and Google report 10-20% in well-optimised products.
Why are so many A/B tests inconclusive?
Roughly 40-45% of tests return no measurable effect in either direction. That’s not the same as wasted. An inconclusive result on a strongly held hypothesis is still genuinely useful information, but most programmes file it as a non-event rather than writing it up.
Is the barrier to acting on test data mostly technical or cultural?
Overwhelmingly cultural rather than technical. NewVantage Partners’ survey of large company data executives found only 24% describe their organisation as data driven, and around 80% say the main barrier is human, process and culture, not technology.
What happens to losing or inconclusive tests in most testing programmes?
They typically get zero write up. Since 80-90% of tests fall into the loss or inconclusive bucket, that’s the majority of a programme’s potential organisational learning being discarded by default.
What actually needs to change for test results to influence strategy?
The piece argues that four things need to change. A shared, searchable evidence library needs to replace results left sitting in individual tool accounts. Each test’s metric needs a clear translation into the business metric stakeholders actually track. Losing and inconclusive tests need write ups, not just the wins. And there needs to be a regular cadence for reviewing patterns across tests, rather than treating each one in isolation.
Sources
- Optimizely, “Top 10 takeaways from running 127,000 experiments,” win rate and category-impact benchmarks (2026). optimizely.com
- Kohavi & Thomke, “The Surprising Power of Online Experiments,” Harvard Business Review (September-October 2017): the Bing headline experiment and experimentation culture. hbr.org
- Davenport & Bean, “Action and Inaction on Data, Analytics, and AI,” MIT Sloan Management Review (2023), citing the NewVantage Partners survey: data culture and organisational barrier statistics.
- Gupta, Kohavi et al., “Online Experimentation: Benefits, Operational and Methodological Challenges, and Scaling Guide,” Harvard Data Science Review (2022): the 10-20% positive effect benchmark and cultural and organisational scaling challenges.
- Qatalog workplace information access study, via 360Learning: knowledge retrieval statistics.
- Blend Commerce, “A/B Testing Benchmarks for eCommerce,” consolidated industry win rate data (2026).
- DRIP Agency, “A/B Testing Statistics 2026,” proprietary e-commerce experiment database.
- roast.page, “A/B Testing Statistics 2026,” hypothesis documentation and top-performer benchmark data.